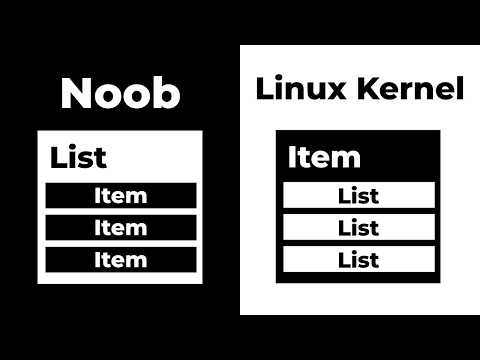
Pointer-to-Pointer (Node**) & Circular Sentinel Elimination
In a naive singly or doubly linked list, every insertion or deletion checks a special-case branch: if (prev == nullptr) head = curr->next; else prev->next = curr->next;. As Linus Torvalds famously demonstrated, there are two complementary techniques that completely eliminate special-case boundary branches:
- Indirect Pointer-to-Pointer (
Node** pp = &head) for Singly Linked Lists: Instead of tracking a predecessor node pointerNode* prev, track the address of the pointer field that points to the current node:Node** indirect = &head. Advancing moves toindirect = &((*indirect)->next), and unlinking the target node executes*indirect = (*indirect)->nextuniformly—whether the node is the head of the list or in the middle! - Circular Dummy Sentinel Node for Doubly Linked Lists: By maintaining a permanent sentinel node
sentinelinitialized to point to itself (sentinel.next = sentinel.prev = &sentinel), the list is never physically empty. Every real node sits strictly between two validNodestructs (sentinel.nextisfront(),sentinel.previsback()), reducinginsert_between(prev, next, node)andunlink(node)to 4 and 2 unconditional pointer stores respectively.
list_head & The container_of Offset IdentityIn a non-intrusive list (std::list<Task>), inserting a Task allocates a separate heap node containing {prev, next, Task}, and removing a Task* given only its address is $O(N)$ unless you also store a std::list::iterator alongside it. In the Linux kernel's intrusive design, the 16-byte hook struct list_head { list_head *next, *prev; } is embedded directly as a member inside struct Task:
$$\text{addr}(\text{Task}) = \text{addr}(\text{member\_ptr}) - \text{offsetof}(\text{Task},\; \text{member})$$
Because the byte offset of a struct field is a compile-time constant known to the compiler, container_of(ptr, Task, run_list) subtracts that constant integer offset from the list_head* address—recovering the enclosing Task* in zero memory dereferences! Even better, a single Task struct can embed multiple list_head fields (run_queue, all_tasks, wait_list), participating in three doubly linked lists simultaneously with zero heap allocations.
Non-Intrusive vs. Intrusive vs. Arena-Indexed Linked Lists
| List Architecture | Heap Allocations per Insert | Unlink Given T* Pointer |
Multi-List Membership | Cache / Memory Overhead |
|---|---|---|---|---|
Non-Intrusive (std::list<T>) |
1 malloc per node |
$O(N)$ (unless iterator stored) | Requires extra wrapper nodes + pointer indirection | 16B links + 16B allocator header per node |
Intrusive (Linux list_head / Boost.Intrusive) |
0 (embedded in T) |
$O(1)$ direct unlink | Embed $k$ list_head fields in single T |
16B per embedded hook, 0 allocator headers |
32-Bit Index Pool (int32_t next, prev) |
0 (contiguous flat vector) | $O(1)$ by index | Multiple index pairs | 8B links ($50\%$ pointer savings), high L1/TLB locality |
Visualizing Non-Intrusive Heap Scattering vs. Intrusive container_of
Circular Sentinel Doubly Linked List Splice & Unlink
(head.next = first,
head.prev = last)"] <--> B["Node 1
list_head"] B <--> C["Node 2
list_head"] C <--> A
Why is traversing a linked list of $N$ nodes across the heap $20\times$ to $50\times$ slower than scanning an array of $N$ elements? On a modern out-of-order CPU (with a 512-entry Reorder Buffer and 12 execution ports), an array loop computes address base + i * sizeof(T) independently for iterations $i, i+1, \dots, i+15$, issuing up to 10–12 L1/L2 memory loads in parallel (Memory-Level Parallelism, MLP). In a linked list, the address of node $k+1$ (curr = curr->next) is stored inside the payload of node $k$. The CPU cannot even know the virtual address of node $k+1$ until the load for node $k$ returns from L3/DRAM (50–250 cycles later), serializing execution to a strict MLP $= 1$ pointer-chasing stall!
Visualize Phase 1 (Tortoise 1× vs Hare 2× meeting inside cycle of length λ) and Phase 2 (resetting one pointer to head to locate cycle entry μ via x ≡ −c (mod λ)).
Invariant & State
Production Implementation: Intrusive Circular Doubly Linked List & Torvalds Indirect Unlink
#include <cstddef>
#include <cstdint>

// Linux-kernel style intrusive circular doubly-linked list hook
struct IntrusiveListNode {
  IntrusiveListNode* next = this;
  IntrusiveListNode* prev = this;

  void init() noexcept { next = prev = this; }
  bool empty() const noexcept { return next == this; }

  static void link_between(IntrusiveListNode* prev_node,
                           IntrusiveListNode* next_node,
                           IntrusiveListNode* new_node) noexcept {
    new_node->next = next_node;
    new_node->prev = prev_node;
    next_node->prev = new_node;
    prev_node->next = new_node;
  }

  // Insert new_node right before this (if this is sentinel head, this is push_back!)
  void push_back(IntrusiveListNode* new_node) noexcept {
    link_between(this->prev, this, new_node);
  }

  // Insert new_node right after this (if this is sentinel head, this is push_front!)
  void push_front(IntrusiveListNode* new_node) noexcept {
    link_between(this, this->next, new_node);
  }

  // Branchless O(1) self-unlink!
  void unlink() noexcept {
    next->prev = prev;
    prev->next = next;
    next = prev = this;
  }
};

// Compile-time offset arithmetic (C++ equivalent of Linux kernel container_of)
#define CONTAINER_OF(ptr, Type, member)   reinterpret_cast<Type*>(reinterpret_cast<char*>(ptr) - offsetof(Type, member))

// Linus Torvalds's branchless pointer-to-pointer singly linked list removal
struct SinglyNode {
  int val;
  SinglyNode* next;
};

void remove_first_matching(SinglyNode** head_ref, int target) noexcept {
  SinglyNode** indirect = head_ref;
  while (*indirect != nullptr) {
    if ((*indirect)->val == target) {
      *indirect = (*indirect)->next; // Works identically for head node and interior nodes!
      return;
    }
    indirect = &((*indirect)->next);
  }
}next (list_for_each_safe)When iterating over an intrusive or manual linked list and unlinking or freeing nodes inside the loop body, writing for (auto* pos = head.next; pos != &head; pos = pos->next) { pos->unlink(); } causes an immediate infinite loop or Use-After-Free because pos->unlink() overwrites pos->next = pos (or free(pos) poisons pos->next) before the loop increment expression reads pos->next! Always use the Linux kernel's list_for_each_safe(pos, tmp, head) idiom: cache auto* next_node = pos->next; at the very top of the loop body before mutating or freeing pos.